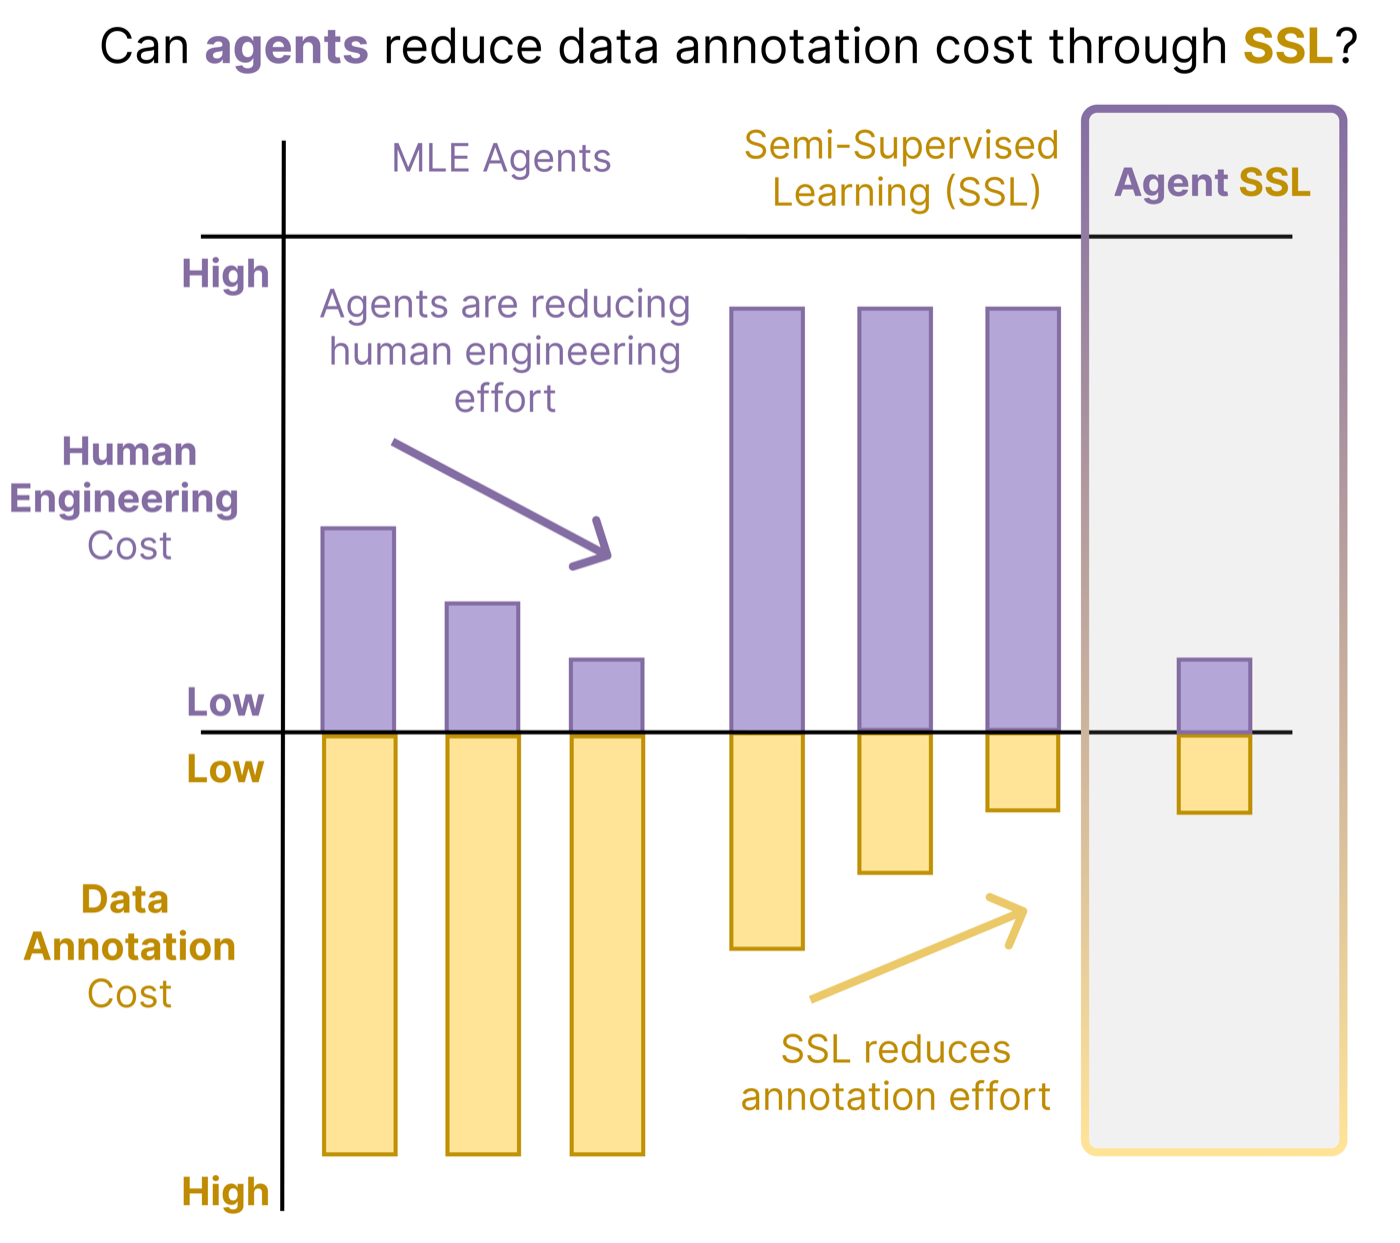
Acquiring high-quality labeled data and engineering effective learning pipelines are two critical bottlenecks to applying machine learning systems in new domains. Although recent MLE agents have shown promise in automating pipeline design, their behavior has been studied almost exclusively in fully supervised settings. In many domains, however, labeled data is expensive while unlabeled data is abundant. In this work, we study agents in the semi-supervised learning (SSL) regime by framing SSL as a program search problem and exploring how agents navigate this space under limited supervision. Our analysis focuses on three questions: (1) whether agents can effectively leverage unlabeled data, (2) how they leverage it and what strategies they discover, and (3) whether they can adapt these strategies to specific domains. We find that agents can leverage and synthesize SSL strategies spanning decades of SSL research, achieving performance comparable to, and in some cases outperforming, established human-engineered SSL methods. We further validate these observations on real-world ecological datasets, highlighting both the challenges and opportunities of transferring agent-discovered strategies beyond controlled benchmarks.
1) AgentSSL: we formulate semi-supervised learning as a structured program-search task for MLE agents.
2) Strong programs: agents autonomously discover SSL programs competitive with, and in several cases outperforming, established SSL baselines.
3) Systematic analysis: agents exploit unlabeled data, explore ideas across classical and modern SSL, and produce diverse, performant solutions.
4) An open problem: we identify reliable program selection as the key bottleneck, with an empirical analysis of existing proxy metrics.
5) Real-world ecology: we evaluate AgentSSL on animal detection tasks, showing both the potential and the challenges of reducing annotation cost in practice.
We frame SSL as a program search problem using LLM-based agents.
Given a small labeled set and a larger unlabeled corpus, an LLM-based agent writes SSL programs. Each program is scored by an evaluator using either unsupervised SSL metrics or noisy validation feedback, and that fitness guides iterative refinement (Phase I). From the resulting candidate programs, one must then be selected without access to test labels (Phase II).
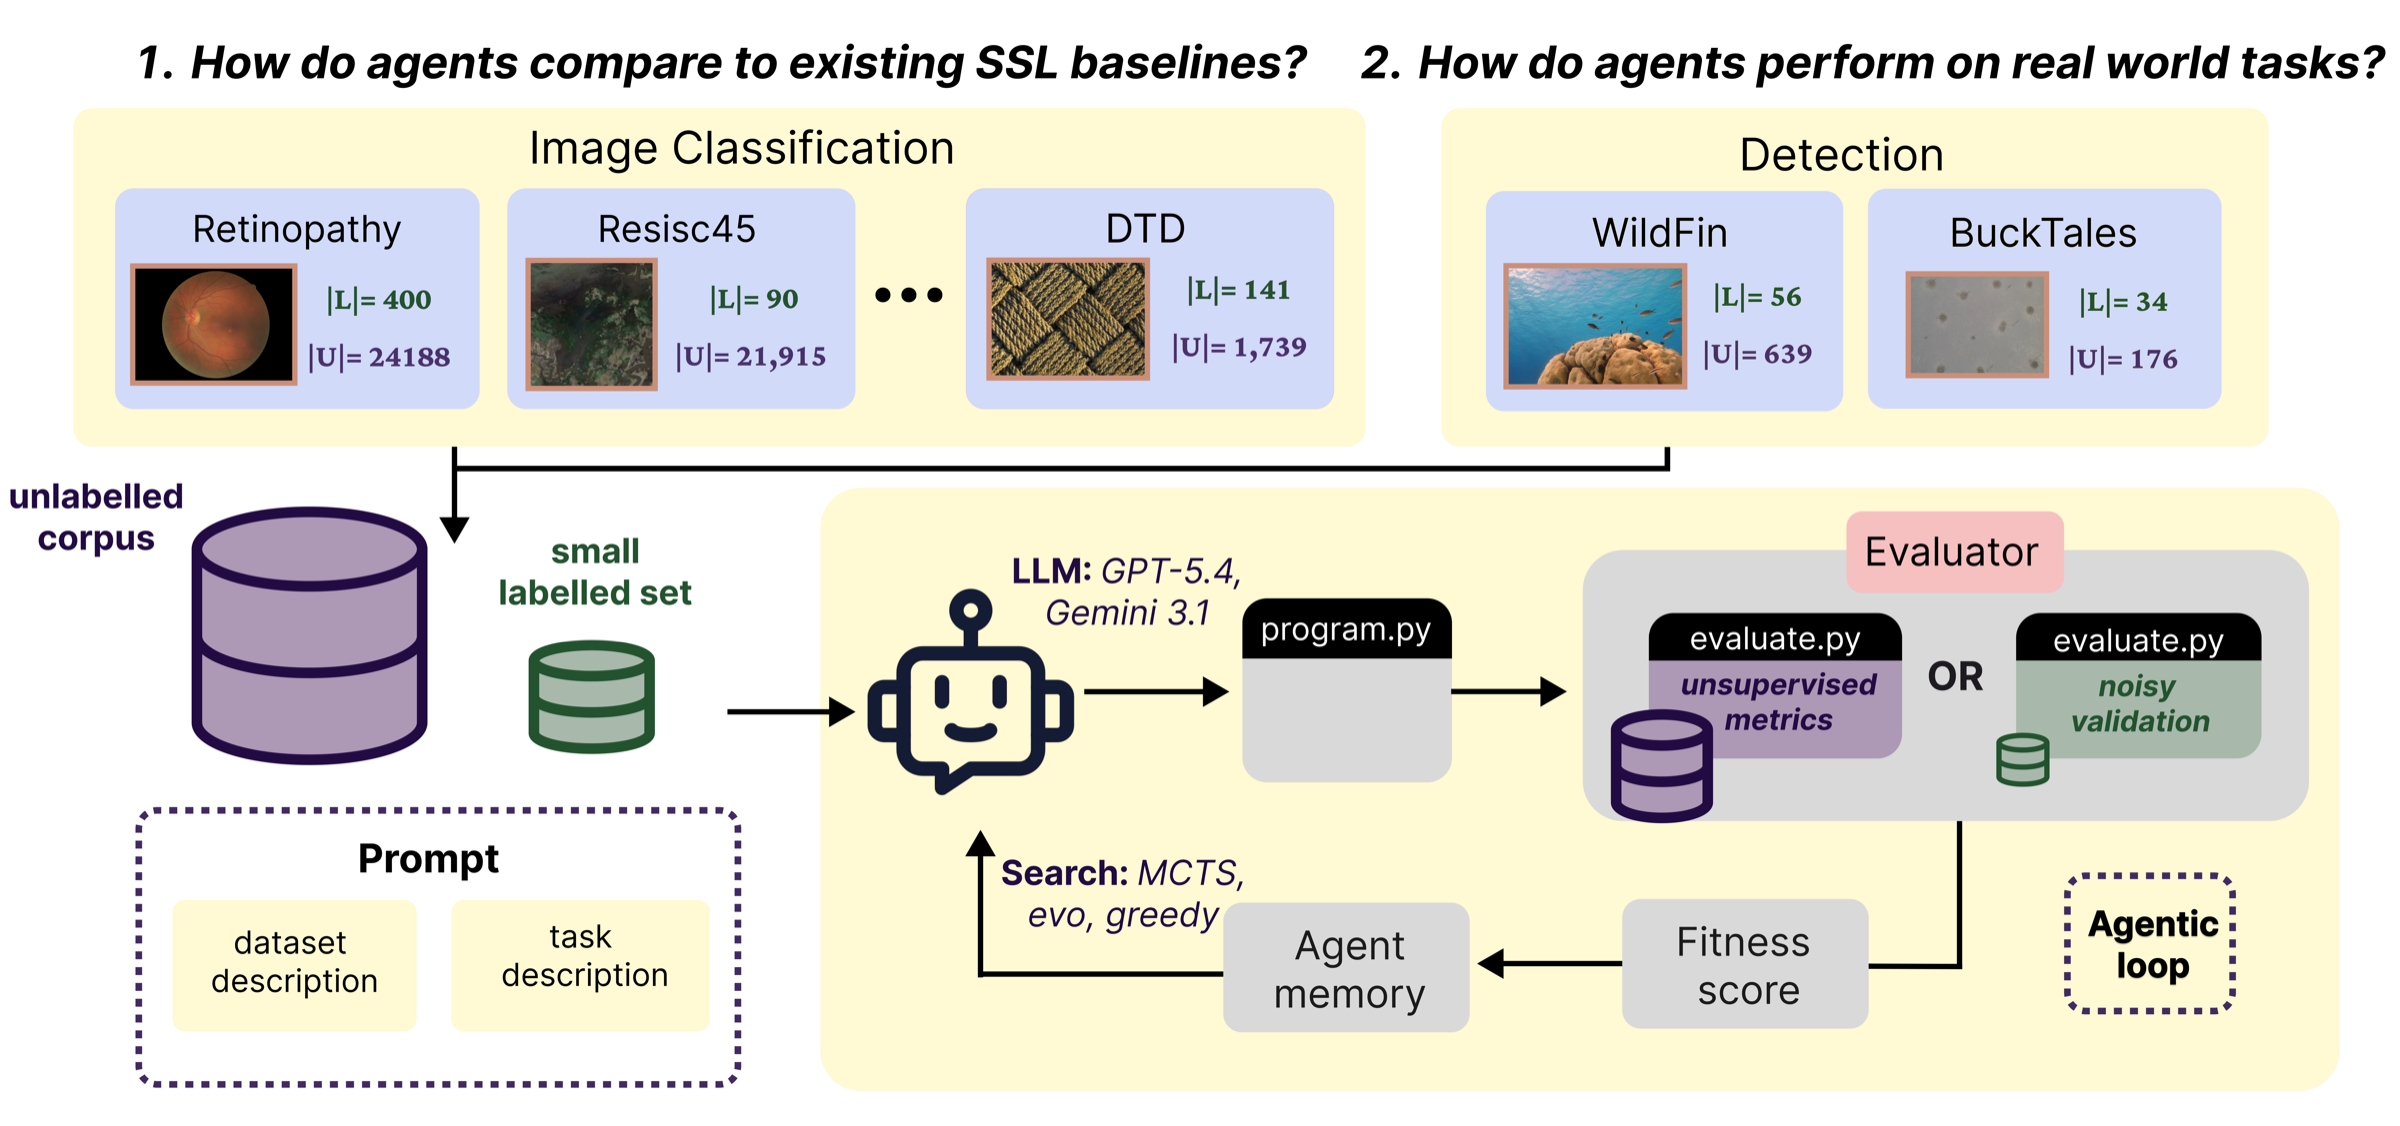
We evaluate AgentSSL on six image-classification SSL benchmarks (DTD, SUN397, RESISC45, Retinopathy, CLEVR, KITTI) and two real-world ecological detection tasks (WildFin, BuckTales).
Across datasets and shot settings, the best agent solution (Abest) is generally comparable to the best human-engineered SSL baseline (Hbest), and outperforms it on several, by up to +15.8 points on Retinopathy.
| DTD | SUN397 | RESISC45 | RETINO | CLEVR | KITTI | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | 3 | 6 | 3 | 6 | 1 | 2 | 40 | 80 | 10 | 20 | 5 | 10 |
| Supervised | 58.35 | 66.68 | 62.06 | 68.74 | 56.08 | 71.11 | 53.86 | 57.64 | 40.30 | 48.24 | 45.05 | 47.07 |
| FixMatch | 58.16 | 67.09 | 56.72 | 64.22 | 62.13 | 81.61 | 38.72 | 41.66 | 38.93 | 56.32 | 39.76 | 43.09 |
| SoftMatch | 62.59 | 69.17 | 69.63 | 73.18 | 73.83 | 86.54 | 45.95 | 54.83 | 46.48 | 67.83 | 37.79 | 43.04 |
| PET | 60.64 | 67.92 | 63.63 | 68.19 | 64.16 | 77.88 | 26.47 | 37.97 | 33.34 | 34.31 | 39.01 | 42.99 |
| V-PET | 64.84 | 70.25 | 66.58 | 71.70 | 62.99 | 77.16 | 20.45 | 29.60 | 32.57 | 33.60 | 39.66 | 37.04 |
| AgentSSLavgU | 65.44 | 72.32 | 67.09 | 70.86 | 71.53 | 78.10 | 40.98 | 63.59 | 35.58 | 43.68 | 47.35 | 47.40 |
| AgentSSLavgN | 65.57 | 71.45 | 66.26 | 70.59 | – | 76.06 | 56.62 | 58.79 | 42.36 | 42.65 | 42.71 | 45.85 |
| AgentSSLmaxU | 68.44 | 73.79 | 68.57 | 72.78 | 76.20 | 80.94 | 41.54 | 55.02 | 44.04 | 45.87 | 40.09 | 47.53 |
| AgentSSLmaxN | 64.71 | 72.10 | 69.12 | 71.15 | – | 76.90 | 36.97 | 73.47 | 48.99 | 53.36 | 39.19 | 42.84 |
| Abest − Hbest | +3.60 | +3.54 | −0.51 | −0.40 | +3.37 | −5.60 | +2.76 | +15.83 | +2.51 | −14.47 | +2.30 | +0.46 |
Few-shot accuracy (oracle test-set selection) by dataset and labels per class. Best human-engineered SSL baseline per column in purple, best agent result in gold. U: unsupervised-metric feedback; N: noisy-validation feedback; avg/max: mean / best over runs.
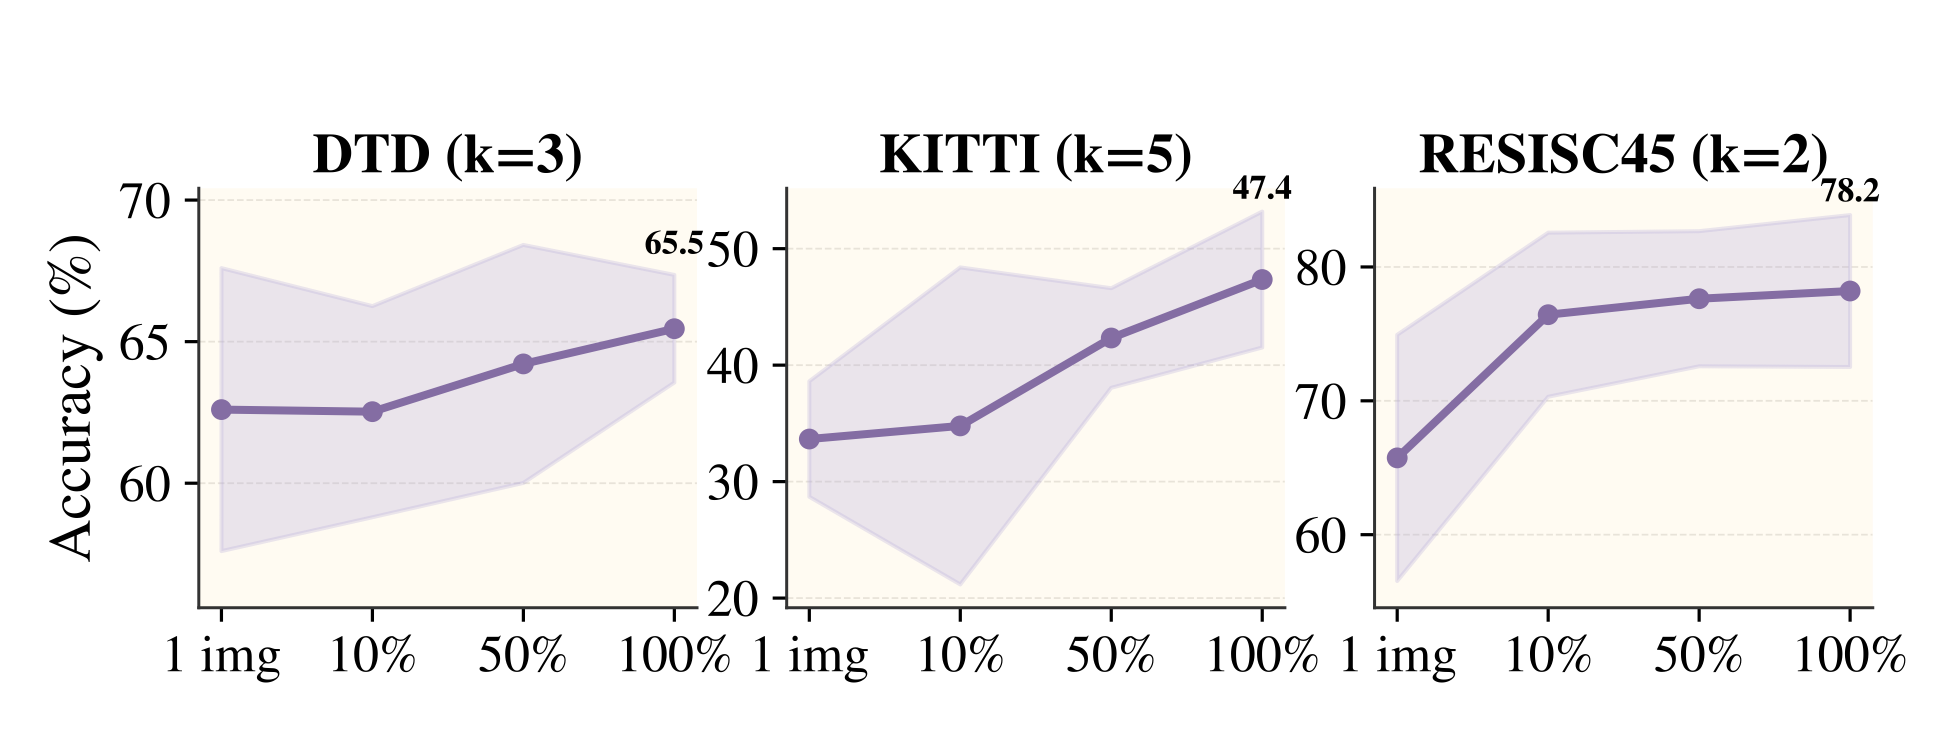
We fix the top program discovered by AgentSSL and vary only the size of the unlabeled corpus at evaluation time. Performance generally improves as more unlabeled data becomes available while the labeled set stays fixed, so the discovered programs rely on structure in the unlabeled data itself.
Rather than converging to a single method family, agents explore a broad range of SSL paradigms, from pseudo-labeling and consistency regularization to graph-based methods, and often combine several within one program. The resulting programs are also complementary: high-performing programs built on different SSL strategies confidently pseudolabel different subsets of the unlabeled images.
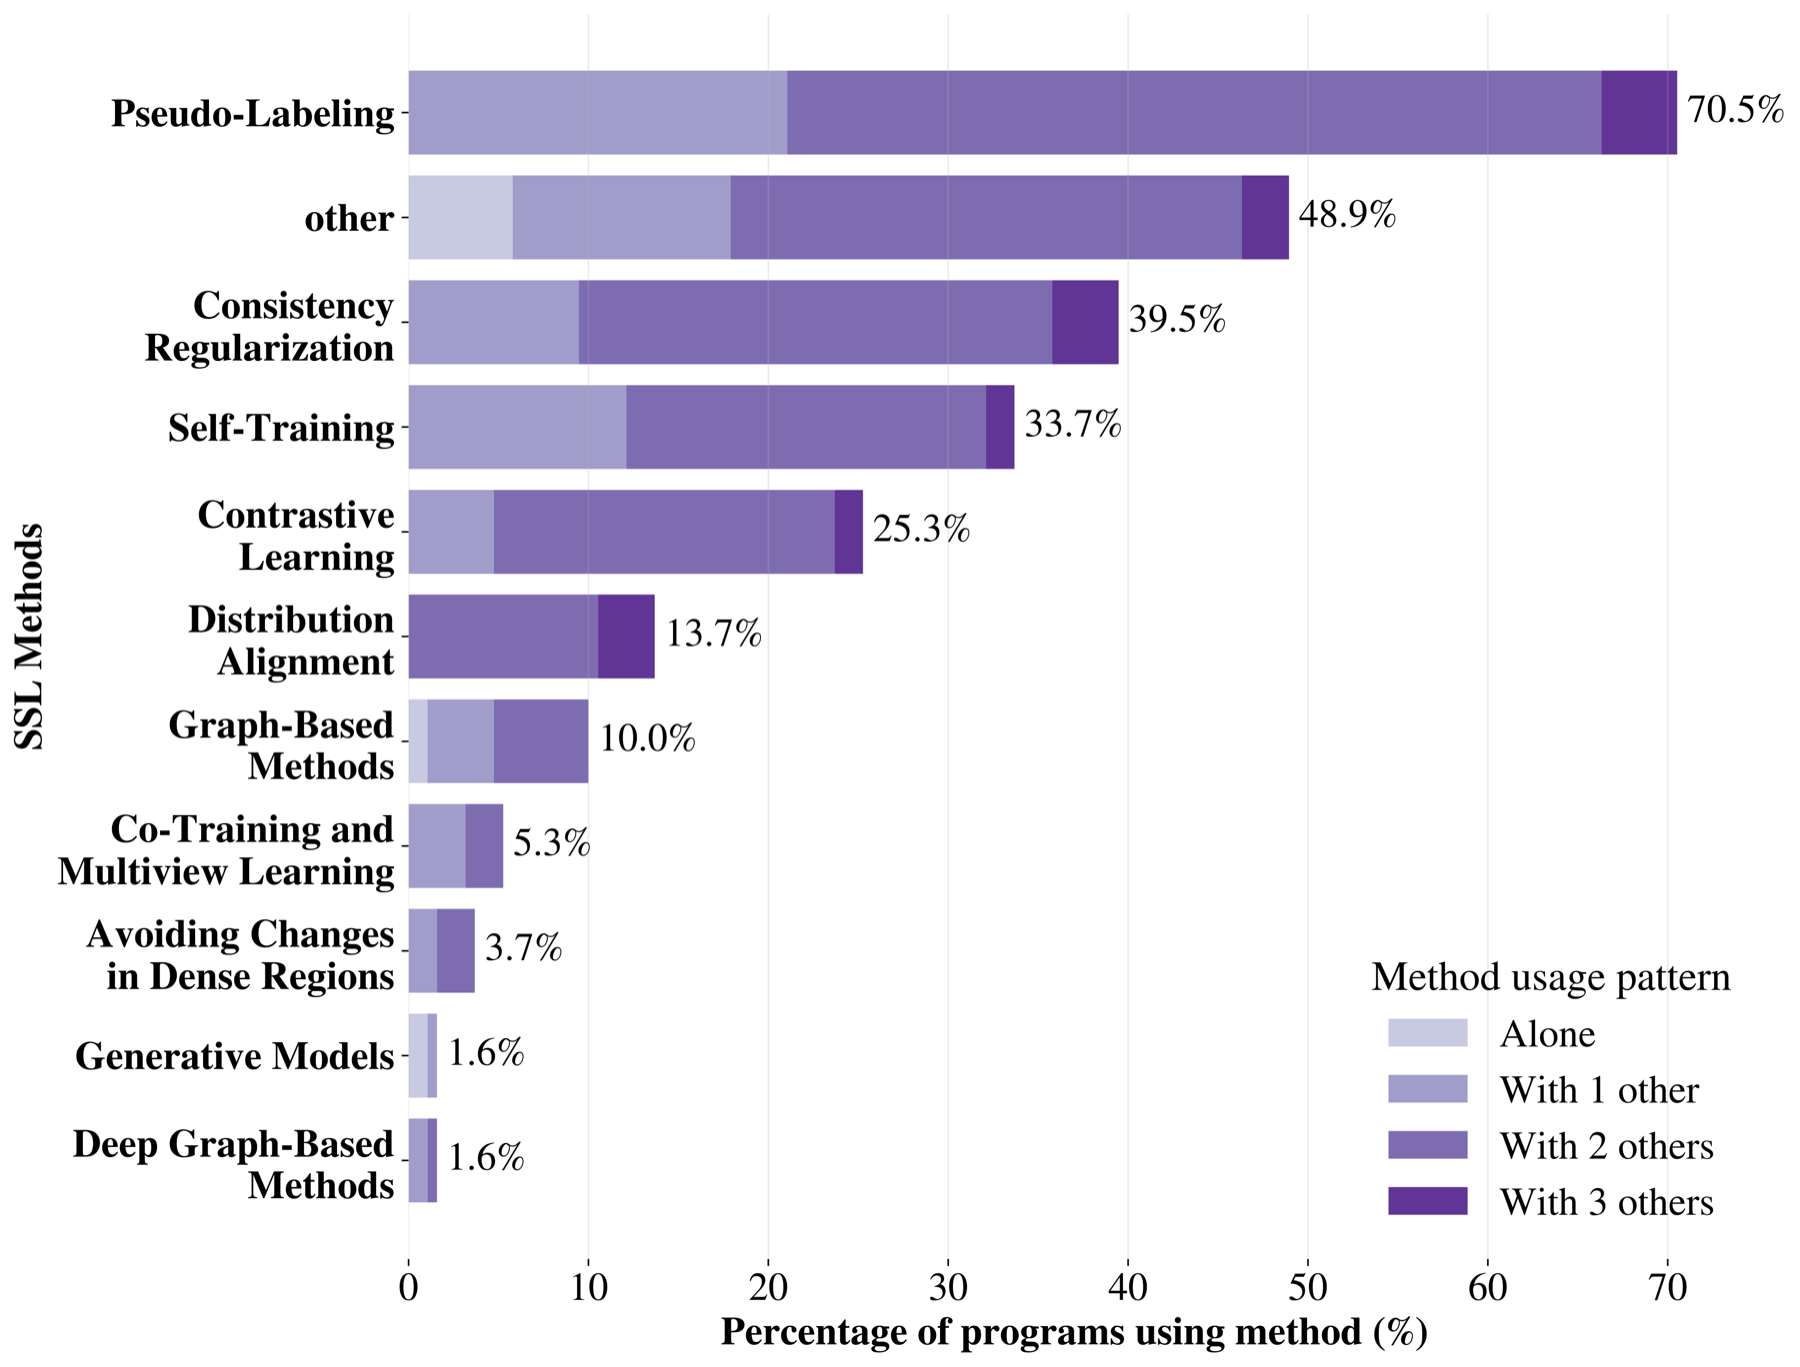
SSL method families explored across all rollouts on DTD (evolutionary search).
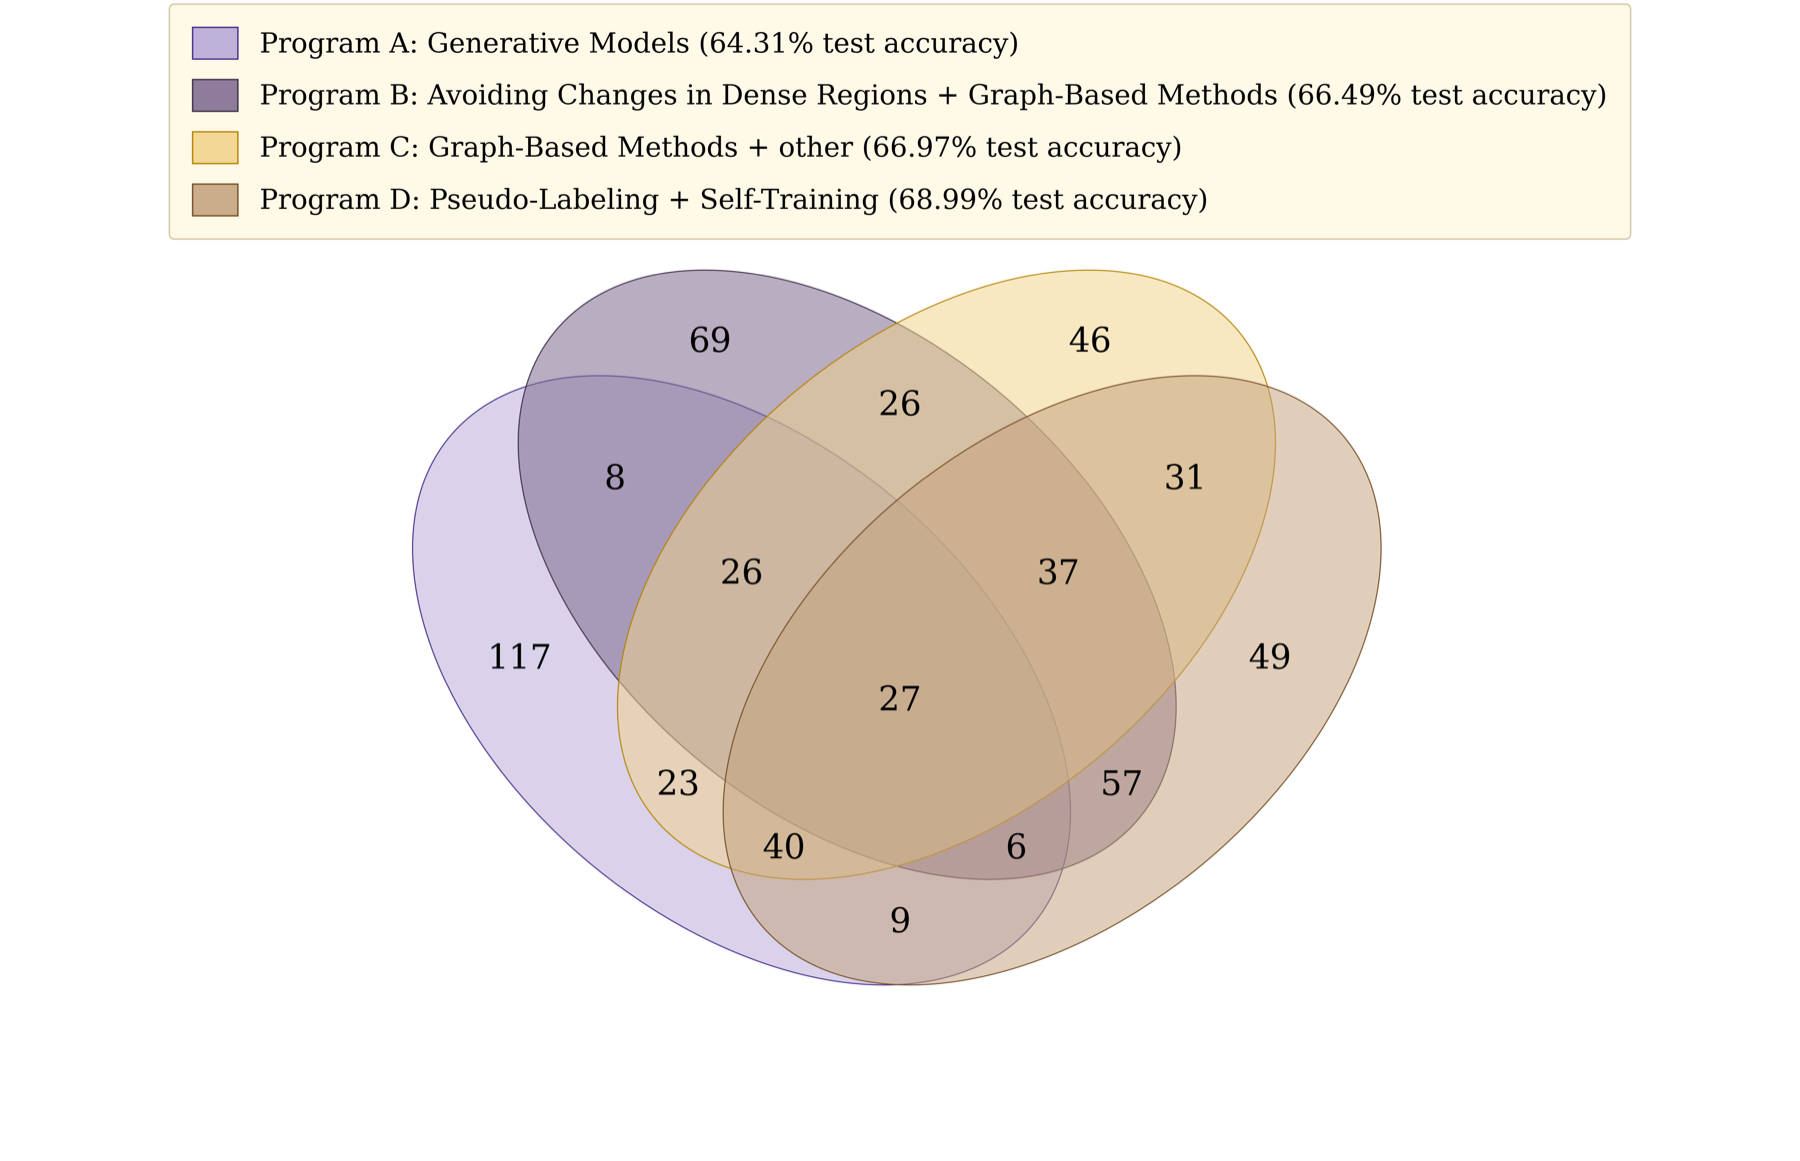
Overlap of each program's top-20% most confident pseudolabels on unlabeled DTD.
Agents can discover dataset-specific strategies instead of relying on one fixed SSL recipe. The best program for each dataset does not generalize to other datasets, evidence that it is tailored to its own domain.

Change in accuracy relative to in-domain performance (rows: source dataset; columns: target).
from __future__ import annotations
import json
import os
from typing import List, Tuple

import torch
import torch.nn.functional as F
from torch.utils.data import Dataset, DataLoader
import torchvision.transforms as T
from PIL import Image


def _read_json(path: str):
    with open(path, "r") as f:
        return json.load(f)


def _coco_label_mapping(train_ann_file: str):
    coco = _read_json(train_ann_file)
    cat_ids = sorted(c["id"] for c in coco["categories"])
    cat_id_to_idx = {cid: i for i, cid in enumerate(cat_ids)}
    idx_to_cat_id = {i: cid for cid, i in cat_id_to_idx.items()}
    return cat_id_to_idx, idx_to_cat_id, len(cat_ids)


def _labeled_records(img_dir: str, train_ann_file: str, cat_id_to_idx: dict):
    coco = _read_json(train_ann_file)
    id_to_name = {img["id"]: img["file_name"] for img in coco["images"]}
    out = []
    for ann in coco["annotations"]:
        fn = id_to_name.get(ann["image_id"])
        if fn is None:
            continue
        path = os.path.join(img_dir, fn)
        if not os.path.isfile(path):
            continue
        cid = ann["category_id"]
        if cid not in cat_id_to_idx:
            continue
        out.append((path, cat_id_to_idx[cid]))
    return out


def _unlabeled_records(img_dir: str, unlabel_ann_file: str):
    coco = _read_json(unlabel_ann_file)
    out = []
    for img in coco["images"]:
        fn = img["file_name"]
        path = os.path.join(img_dir, fn)
        if os.path.isfile(path):
            out.append(path)
    return out


class _ImageOnlyDataset(Dataset):
    def __init__(self, paths, transform):
        self.paths = paths
        self.transform = transform

    def __len__(self):
        return len(self.paths)

    def __getitem__(self, idx):
        img = Image.open(self.paths[idx]).convert("RGB")
        return self.transform(img)


class _GraphConfig:
    def __init__(
        self,
        k_ul: int = 24,
        k_uu: int = 24,
        temperature: float = 0.07,
        alpha: float = 0.85,
        iters: int = 25,
        chunk_q: int = 1024,
    ):
        self.k_ul = k_ul
        self.k_uu = k_uu
        self.temperature = temperature
        self.alpha = alpha
        self.iters = iters
        self.chunk_q = chunk_q


class ClassificationAgent:
    NET_NAME = "timm/vit_base_patch14_reg4_dinov2.lvd142m"

    def __init__(self, net_builder_fn, get_peft_config_fn, num_classes):
        self.net_builder_fn = net_builder_fn
        self.get_peft_config_fn = get_peft_config_fn
        self.num_classes = num_classes
        self.device = torch.device("cuda" if torch.cuda.is_available() else "cpu")

        self.img_size = 224
        self.transform = self._eval_transform(self.img_size)
        self.idx_to_cat_id = {i: i for i in range(num_classes)}

        peft_config = self.get_peft_config_fn({"freeze_backbone": True})
        vit_config = {"drop_path_rate": 0.0}
        net_builder = self.net_builder_fn(self.NET_NAME, peft_config, vit_config)
        self.model = net_builder(
            num_classes=num_classes, pretrained=True, pretrained_path=""
        ).to(self.device)
        self.model.eval()

        self.graph_cfg = _GraphConfig()

        self.train_feat = None
        self.train_labels = None
        self.train_prop = None
        self.class_prototypes = None
        self.residual_quantiles = None

        self.k_query = 32
        self.k_proto = 5
        self.tta_shift = 8

        self.fuse_w_knn_hard = 1.15
        self.fuse_w_knn_prop = 0.85
        self.fuse_w_proto = 0.55
        self.fuse_w_ord = 0.30
        self.score_temp = 0.07
        self.proto_temp = 0.09
        self.conformal_q = 0.80

    def _eval_transform(self, img_size=224):
        resize = int(img_size * 256 / 224)
        return T.Compose(
            [
                T.Resize(resize, interpolation=T.InterpolationMode.BICUBIC),
                T.CenterCrop(img_size),
                T.ToTensor(),
                T.Normalize(
                    mean=[0.485, 0.456, 0.406],
                    std=[0.229, 0.224, 0.225],
                ),
            ]
        )

    @torch.no_grad()
    def _extract_features(self, paths, batch_size=64):
        if len(paths) == 0:
            return torch.empty((0, 768), dtype=torch.float32)

        ds = _ImageOnlyDataset(paths, self.transform)
        loader = DataLoader(
            ds,
            batch_size=min(batch_size, max(1, len(ds))),
            shuffle=False,
            num_workers=min(8, os.cpu_count() or 0),
            pin_memory=self.device.type == "cuda",
            drop_last=False,
        )

        feats = []
        for x in loader:
            x = x.to(self.device, non_blocking=True)
            out = self.model(x)
            feats.append(out["feat"].detach().cpu())
        if len(feats) == 0:
            return torch.empty((0, 768), dtype=torch.float32)
        return torch.cat(feats, dim=0)

    def _build_sparse_neighbors(self, xu: torch.Tensor, xl: torch.Tensor):
        cfg = self.graph_cfg
        device = self.device
        xu = xu.to(device)
        xl = xl.to(device)

        Nu = xu.shape[0]
        Nl = xl.shape[0]
        if Nu == 0 or Nl == 0:
            raise RuntimeError(
                "Neighbor graph requires both labeled and unlabeled features."
            )

        k_ul = min(cfg.k_ul, Nl)
        k_uu = min(cfg.k_uu + 1, Nu)

        ul_idx_parts, ul_w_parts = [], []
        uu_idx_parts, uu_w_parts = [], []

        for start in range(0, Nu, cfg.chunk_q):
            end = min(start + cfg.chunk_q, Nu)
            q = xu[start:end]

            sim_ul = q @ xl.T
            vals_ul, idx_ul = torch.topk(sim_ul, k=max(1, k_ul), dim=1)
            w_ul = torch.softmax(vals_ul / cfg.temperature, dim=1)
            ul_idx_parts.append(idx_ul.cpu())
            ul_w_parts.append(w_ul.cpu())

            if Nu == 1:
                idx_uu = torch.zeros((end - start, 1), dtype=torch.long, device=device)
                vals_uu = torch.zeros(
                    (end - start, 1), dtype=torch.float32, device=device
                )
            else:
                sim_uu = q @ xu.T
                vals_uu, idx_uu = torch.topk(sim_uu, k=max(2, k_uu), dim=1)
                rows = torch.arange(start, end, device=device).unsqueeze(1)
                keep = idx_uu != rows
                idx_uu = idx_uu[keep].view(end - start, -1)
                vals_uu = vals_uu[keep].view(end - start, -1)
                if idx_uu.shape[1] == 0:
                    idx_uu = torch.zeros(
                        (end - start, 1), dtype=torch.long, device=device
                    )
                    vals_uu = torch.zeros(
                        (end - start, 1), dtype=torch.float32, device=device
                    )
                else:
                    idx_uu = idx_uu[:, : min(cfg.k_uu, idx_uu.shape[1])]
                    vals_uu = vals_uu[:, : min(cfg.k_uu, vals_uu.shape[1])]

            w_uu = torch.softmax(vals_uu / cfg.temperature, dim=1)
            uu_idx_parts.append(idx_uu.cpu())
            uu_w_parts.append(w_uu.cpu())

        ul_idx = torch.cat(ul_idx_parts, dim=0)
        ul_w = torch.cat(ul_w_parts, dim=0)
        uu_idx = torch.cat(uu_idx_parts, dim=0)
        uu_w = torch.cat(uu_w_parts, dim=0)
        return ul_idx, ul_w, uu_idx, uu_w

    def _label_propagation(self, xl: torch.Tensor, yl: torch.Tensor, xu: torch.Tensor):
        num_classes = self.num_classes
        cfg = self.graph_cfg

        xl = F.normalize(xl.float(), dim=1)
        xu = F.normalize(xu.float(), dim=1)

        y_onehot = F.one_hot(yl, num_classes=num_classes).float()
        ul_idx, ul_w, uu_idx, uu_w = self._build_sparse_neighbors(xu, xl)

        yu = torch.full(
            (xu.shape[0], num_classes), 1.0 / num_classes, dtype=torch.float32
        )

        for _ in range(cfg.iters):
            msg_l = torch.sum(ul_w.unsqueeze(-1) * y_onehot[ul_idx], dim=1)
            msg_u = torch.sum(uu_w.unsqueeze(-1) * yu[uu_idx], dim=1)
            yu = (1.0 - cfg.alpha) * msg_l + cfg.alpha * msg_u
            yu = yu / yu.sum(dim=1, keepdim=True).clamp_min(1e-8)

        return y_onehot, yu

    def _compute_train_propagated_probs(
        self, xl: torch.Tensor, yl: torch.Tensor, xu: torch.Tensor, yu: torch.Tensor
    ):
        xl_n = F.normalize(xl.float(), dim=1)
        xu_n = F.normalize(xu.float(), dim=1)
        y_onehot = F.one_hot(yl, num_classes=self.num_classes).float()

        sims_ll = xl_n @ xl_n.T
        sims_lu = xl_n @ xu_n.T

        if xl.shape[0] <= 1:
            msg_ll = y_onehot.clone()
        else:
            k_ll = min(16, xl.shape[0] - 1)
            vals_ll, idx_ll = torch.topk(
                sims_ll, k=min(k_ll + 1, sims_ll.shape[1]), dim=1
            )
            rows = torch.arange(xl.shape[0]).unsqueeze(1)
            keep = idx_ll != rows
            idx_ll = idx_ll[keep].view(xl.shape[0], -1)[:, :k_ll]
            vals_ll = vals_ll[keep].view(xl.shape[0], -1)[:, :k_ll]
            w_ll = torch.softmax(vals_ll / 0.07, dim=1)
            msg_ll = torch.sum(w_ll.unsqueeze(-1) * y_onehot[idx_ll], dim=1)

        if xu.shape[0] == 0:
            msg_lu = torch.full_like(msg_ll, 1.0 / self.num_classes)
        else:
            k_lu = min(32, xu.shape[0])
            vals_lu, idx_lu = torch.topk(sims_lu, k=k_lu, dim=1)
            w_lu = torch.softmax(vals_lu / 0.07, dim=1)
            msg_lu = torch.sum(w_lu.unsqueeze(-1) * yu[idx_lu], dim=1)

        prop = 0.6 * msg_ll + 0.4 * msg_lu
        prop = prop / prop.sum(dim=1, keepdim=True).clamp_min(1e-8)
        return prop

    def _build_prototypes(self, xl: torch.Tensor, yl: torch.Tensor):
        protos = []
        for c in range(self.num_classes):
            mask = yl == c
            if mask.any():
                proto = xl[mask].mean(dim=0)
            else:
                proto = xl.mean(dim=0)
            protos.append(F.normalize(proto, dim=0))
        return torch.stack(protos, dim=0)

    def _fused_local_logits(
        self,
        query_feat: torch.Tensor,
        leave_one_out_index: int | None = None,
    ):
        feat = F.normalize(query_feat.float(), dim=1).cpu()
        train_feat = self.train_feat
        train_labels = self.train_labels
        train_prop = self.train_prop
        prototypes = self.class_prototypes
        num_classes = self.num_classes

        sim = feat @ train_feat.T

        if leave_one_out_index is not None and feat.shape[0] == 1:
            sim[:, leave_one_out_index] = -1e4

        k = min(
            self.k_query,
            train_feat.shape[0] - (1 if leave_one_out_index is not None else 0),
        )
        k = max(1, k)

        vals, idx = torch.topk(sim, k=k, dim=1)
        w = torch.softmax(vals / self.score_temp, dim=1)

        neigh_labels = train_labels[idx]
        hard = F.one_hot(neigh_labels, num_classes=num_classes).float()
        hard_prob = torch.sum(w.unsqueeze(-1) * hard, dim=1)

        prop_prob = torch.sum(w.unsqueeze(-1) * train_prop[idx], dim=1)
        prop_prob = prop_prob / prop_prob.sum(dim=1, keepdim=True).clamp_min(1e-8)

        sim_proto = feat @ prototypes.T
        proto_prob = torch.softmax(sim_proto / self.proto_temp, dim=1)

        class_vals = torch.arange(num_classes, dtype=feat.dtype).unsqueeze(0)
        exp_severity = torch.sum(hard_prob * class_vals, dim=1, keepdim=True)
        ord_bias = -torch.abs(class_vals - exp_severity)

        fused = (
            self.fuse_w_knn_hard * torch.log(hard_prob.clamp_min(1e-8))
            + self.fuse_w_knn_prop * torch.log(prop_prob.clamp_min(1e-8))
            + self.fuse_w_proto * torch.log(proto_prob.clamp_min(1e-8))
            + self.fuse_w_ord * ord_bias
        )
        return fused

    def _build_conformal_residuals(self):
        n = self.train_feat.shape[0]
        residuals = []
        correct = 0
        for i in range(n):
            logits_i = self._fused_local_logits(
                self.train_feat[i : i + 1], leave_one_out_index=i
            )
            probs_i = torch.softmax(logits_i, dim=-1).squeeze(0)
            true_y = int(self.train_labels[i].item())
            true_prob = probs_i[true_y].item()
            residuals.append(1.0 - true_prob)
            if int(torch.argmax(probs_i).item()) == true_y:
                correct += 1

        residuals = torch.tensor(residuals, dtype=torch.float32)
        q = torch.quantile(residuals, self.conformal_q).item()
        self.residual_quantiles = torch.full(
            (self.num_classes,), float(q), dtype=torch.float32
        )
        print(
            f"local_loo_acc={correct / max(n, 1):.4f} "
            f"conformal_q={self.conformal_q:.2f} "
            f"resid_quantile={q:.4f}",
            flush=True,
        )

    def fit(self, img_dir, train_ann_file, unlabel_ann_file):
        cat_id_to_idx, idx_to_cat_id, num_classes = _coco_label_mapping(train_ann_file)
        self.idx_to_cat_id = idx_to_cat_id
        self.num_classes = num_classes

        labeled = _labeled_records(img_dir, train_ann_file, cat_id_to_idx)
        unlabeled = _unlabeled_records(img_dir, unlabel_ann_file)

        if len(labeled) == 0:
            raise RuntimeError("No labeled samples found.")
        if len(unlabeled) == 0:
            raise RuntimeError("No unlabeled samples found.")

        labeled_paths = [p for p, _ in labeled]
        yl = torch.tensor([y for _, y in labeled], dtype=torch.long)

        print(
            f"extract_features labeled={len(labeled_paths)} unlabeled={len(unlabeled)}",
            flush=True,
        )
        xl = self._extract_features(labeled_paths, batch_size=64)
        xu = self._extract_features(unlabeled, batch_size=64)

        xl = F.normalize(xl.float(), dim=1)
        xu = F.normalize(xu.float(), dim=1)

        print("running_label_propagation", flush=True)
        _, yu = self._label_propagation(xl, yl, xu)
        prop_l = self._compute_train_propagated_probs(xl, yl, xu, yu)

        self.train_feat = xl.cpu()
        self.train_labels = yl.cpu()
        self.train_prop = prop_l.cpu()
        self.class_prototypes = self._build_prototypes(
            self.train_feat, self.train_labels
        ).cpu()

        print("building_local_conformal_calibration", flush=True)
        self._build_conformal_residuals()

        with torch.no_grad():
            train_logits = self._fused_local_logits(self.train_feat)
            train_probs = torch.softmax(train_logits, dim=-1)
            train_pred = train_probs.argmax(dim=-1)
            acc = (train_pred == self.train_labels).float().mean().item()
            nll = F.nll_loss(
                torch.log(train_probs.clamp_min(1e-8)), self.train_labels
            ).item()
            print(f"fit_train_acc={acc:.4f} fit_train_nll={nll:.4f}", flush=True)

        self.model.eval()
        print("fit_done", flush=True)

    def _tta_views(self, x: torch.Tensor):
        views = [x]
        views.append(torch.flip(x, dims=[3]))
        s = min(self.tta_shift, x.shape[-1] // 16)
        if s > 0:
            views.append(torch.roll(x, shifts=-s, dims=3))
            views.append(torch.roll(x, shifts=s, dims=3))
        return views

    @torch.no_grad()
    def _predict_from_feat(self, feat: torch.Tensor):
        raw_logits = self._fused_local_logits(feat).to(self.device)
        probs = torch.softmax(raw_logits, dim=-1)

        penalty = self.residual_quantiles.to(self.device).unsqueeze(0)
        calibrated_probs = (probs - penalty).clamp_min(1e-8)
        calibrated_probs = calibrated_probs / calibrated_probs.sum(
            dim=1, keepdim=True
        ).clamp_min(1e-8)
        calibrated_logits = torch.log(calibrated_probs.clamp_min(1e-8))
        return calibrated_logits

    @torch.no_grad()
    def predict(self, image_batch):
        self.model.eval()

        if (
            self.train_feat is None
            or self.train_prop is None
            or self.residual_quantiles is None
        ):
            raise RuntimeError("Call fit() before predict().")

        if isinstance(image_batch, torch.Tensor):
            x = image_batch
            if x.ndim == 3:
                x = x.unsqueeze(0)
            x = x.float().to(self.device, non_blocking=True)
        elif isinstance(image_batch, list):
            x = torch.stack(
                [self.transform(im.convert("RGB")) for im in image_batch], dim=0
            ).to(self.device, non_blocking=True)
        else:
            raise TypeError("image_batch must be a Tensor or list of PIL images")

        views = self._tta_views(x)
        logits_sum = None
        feat_main = None

        for i, xv in enumerate(views):
            out = self.model(xv)
            feat = F.normalize(out["feat"].float(), dim=1)
            if i == 0:
                feat_main = feat
            logits_v = self._predict_from_feat(feat)
            logits_sum = logits_v if logits_sum is None else (logits_sum + logits_v)

        logits = logits_sum / float(len(views))
        pred_idx = logits.argmax(dim=-1).detach().cpu().tolist()
        predictions = [{"category_id": int(self.idx_to_cat_id[i])} for i in pred_idx]
        return logits, feat_main, predictions
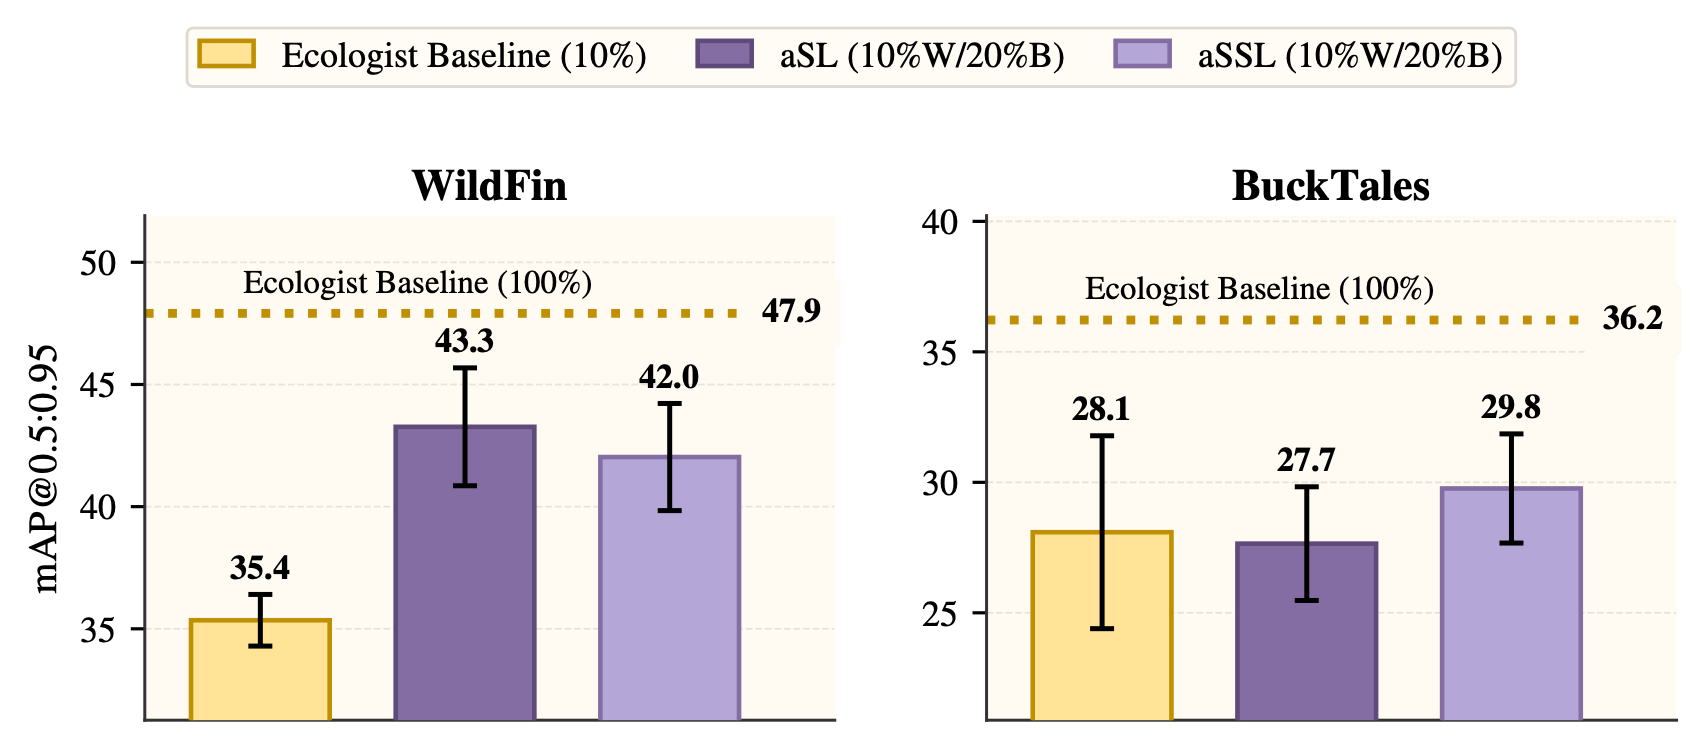
We evaluate AgentSSL on animal detection from two ecological pipelines, WildFin (fish) and BuckTales (antelope), against the domain experts' YOLOv8 pipelines using small labeled subsets.
On WildFin, agents outperform the low-label expert baseline and approach the full-data pipeline. On BuckTales they only match it: the expert solution relies on very high-resolution inputs, while agents spend their budget on more complex tiling and SSL strategies.
Citation coming soon.